About

I am pursuing a master’s degree in Computer Science at the University of Illinois Urbana-Champaign, after earning my bachelor’s degree in Computer Science and Applied Mathematics from the University of Washington.

I am currently open to internship opportunities across software engineering, machine learning, and related fields.

📖 Education

  • University of Illinois Urbana-Champaign, 2026.09 - 2028.06 (expected)
    Master of Science in Computer Science

  • University of Washington, 2022.09 - 2026.03
    Bachelor of Science in Computer Science
    Bachelor of Science in Applied Mathematics: Data Science

💼 Work Experience

  • United Automotive Electronic Systems (UAES) – Bosch JV, Jun - Aug 2026
    Algorithm Engineer Intern
    • Developed an automated OmniDocBench-based evaluation and data feedback framework for structured information extraction from automotive technical documents; integrated LLM-based logical validation, image-encoder features, unsupervised clustering, and targeted human annotation to identify high-value error cases and reduce redundant labeling.

    • Designed comparative experiments across model versions and document categories, evaluating the parsing of text, formulas, tables, and reading order; conducted error analysis to guide model iteration, improving the overall parsing score from 86.86 to 91.72, a 5.6% relative increase.

    • Collaborated with model R&D, data annotation, and engineering teams, delivering model performance reports, prioritized error cases, and curated training samples based on evaluation results; packaged the parsing pipeline as a FastAPI service and authored evaluation metric documentation, an internal usage guide, and a comprehensive project report.

  • iFLYTEK Co., Ltd., Jul - Sep 2025
    Algorithm Engineer Intern
    • Developed and optimized reusable Python and Bash scripts to transform raw multilingual speech corpora into feature representations for large-scale TTS model training; orchestrated x-vector extraction, Wav2Vec-based VQ-code generation, prosody analysis, PyDur-based duration processing, and MFA phoneme alignment, processing nearly 800,000 utterances.

    • Designed a variance-based speech quality detection method to identify low-energy trailing segments and waveform-boundary anomalies; benchmarked it against the existing RMS-based method on manually reviewed multilingual samples and tuned boundary windows and detection thresholds, reducing the false-negative rate from 31% to approximately 22%.

    • Collaborated with data and speech-modeling teams to address feature and data-quality requirements for model training, delivering model-ready multilingual datasets and data-quality analyses; communicated experimental results and data-processing progress through weekly reviews.

  • Fudan University, Jun–Sep 2024
    Research Assistant
    • Professor Wei Wang’s team participation, literature search, pollutant information extraction OCR research, model analysis, program design, project work report under the guidance of the professor. See below for details.
  • Shanghai Chengdian Fuzhi Technology Co., Ltd., Jun–Sep 2023
    Project Assistant
    • Database design for intelligent parking system, documentation of intelligent system design, system development specifications and database specifications, project management assisting.

🏅 Projects

• Wordplay: An Interactive Programming Language for Multilingual and Inclusive Expression
UW iSchool & Allen School
Participating in the development and testing of Wordplay, an interactive programming language designed for multilingual users and people with disabilities. Working on responsive data flow modules, graphical and interactive programming features, and contributed to an adaptable programming prototype. Regularly reported project progress, discussed human-computer interaction research topics, and summarized experimental findings.
Languages & Tools: JavaScript, TypeScript, HTML, CSS, Svelte/SvelteKit

• Multilingual Character-Level Language Model for Next-Character Prediction
Developed a multilingual character-level language prediction model for next-character prediction under low-resource and noisy text scenarios. Proposed a hybrid framework combining a character-level Transformer with a statistical N-gram language model, using weighted score fusion to improve prediction robustness and stability across multilingual inputs.
Implemented an end-to-end training and inference pipeline with AdamW optimization and a cosine annealing learning rate schedule with warmup, improving training stability and convergence efficiency. Processed multilingual datasets and evaluated model performance through prediction accuracy and experimental comparison.
Languages & Tools: Python, PyTorch, Transformer

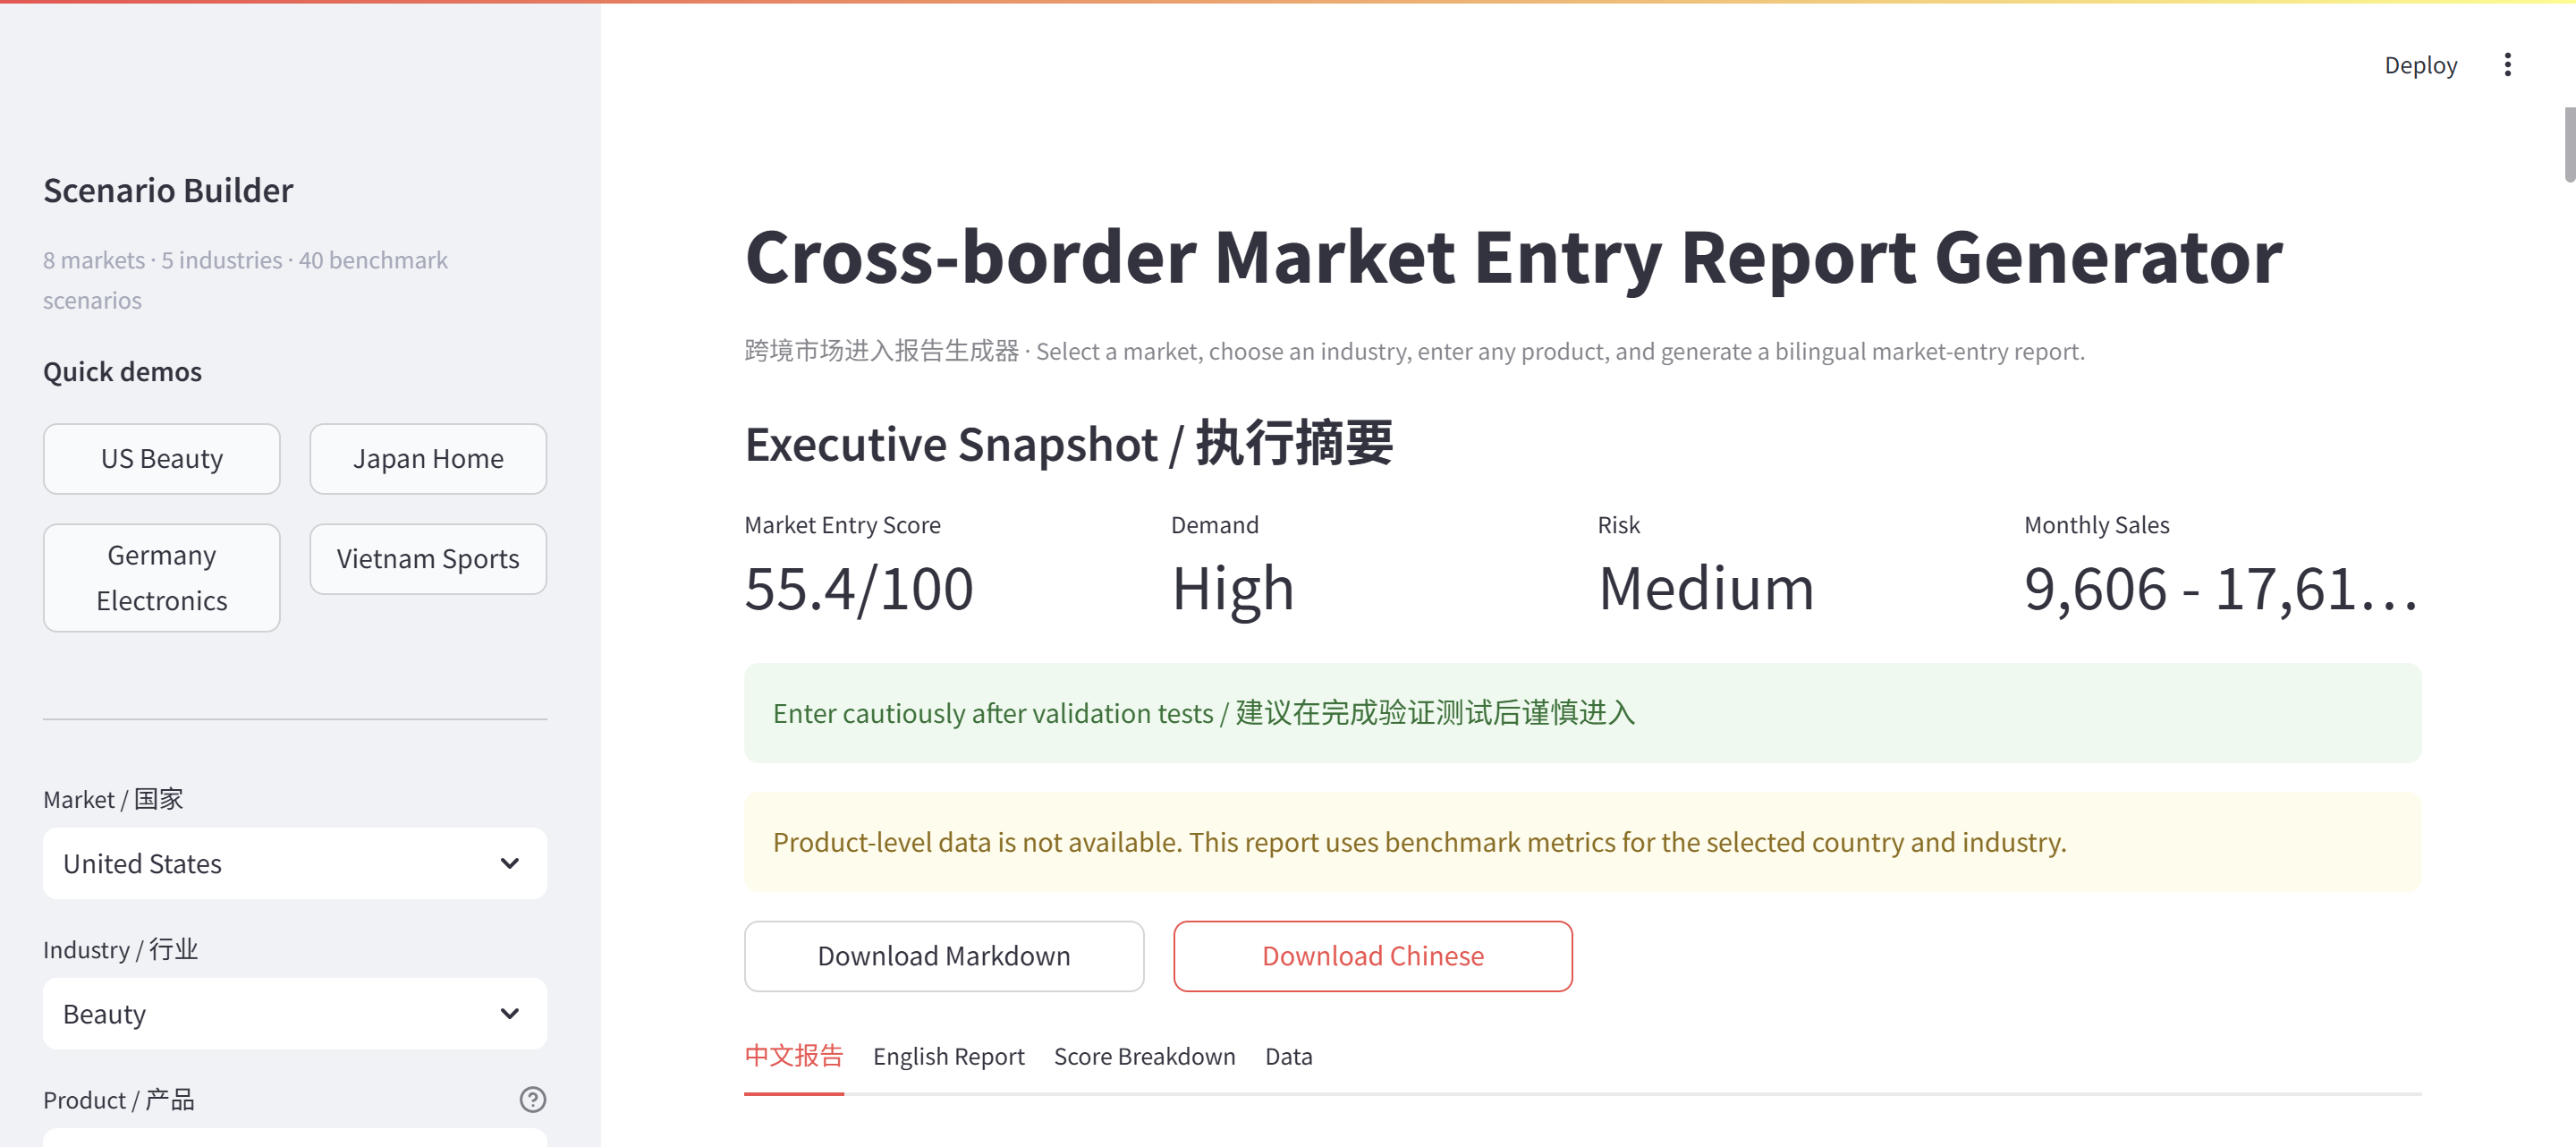
• MarketPilot AI: Market Entry Decision Support
Multi-Agent Workflow
Developed a modular market-entry analysis system that helps cross-border sellers evaluate overseas product opportunities. Integrated planning, retrieval, and reporting agents with rule-based demand forecasting, risk assessment, and a weighted Market Entry Score to generate explainable business recommendations.
Built an Excel-to-CSV/JSON/SQLite data pipeline with source metadata and benchmark scenarios covering 8 markets and 5 industries. Supported free-form product queries with clearly labeled industry-benchmark fallback when exact product data is unavailable. Deployed an interactive Streamlit demo with English and Chinese reports, report previews, and Markdown downloads.
Languages & Tools: Python, pandas, openpyxl, SQLite, Streamlit, pytest

• YOLO-World for Open-Vocabulary Object Detection
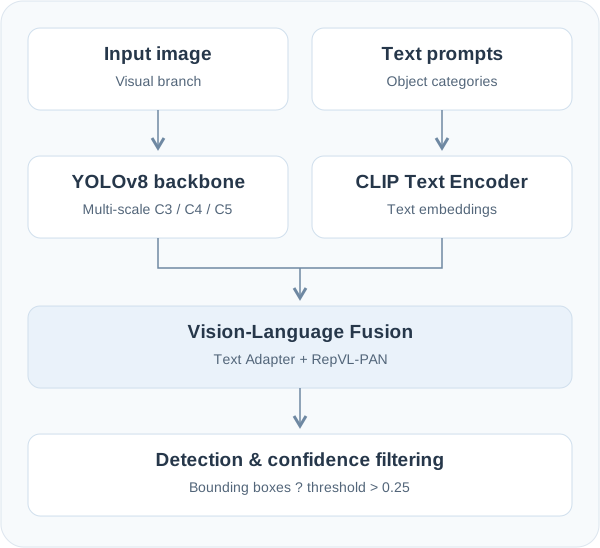
Built an open-vocabulary object detection system covering text encoding, visual feature extraction, and cross-modal fusion. Integrated a YOLOv8-based CNN backbone, a CLIP Text Encoder, and a lightweight RepVL-PAN module to jointly model multi-scale visual features and text embeddings. Used a Text Adapter to modulate C3/C4/C5 features under textual guidance for cross-modal alignment.
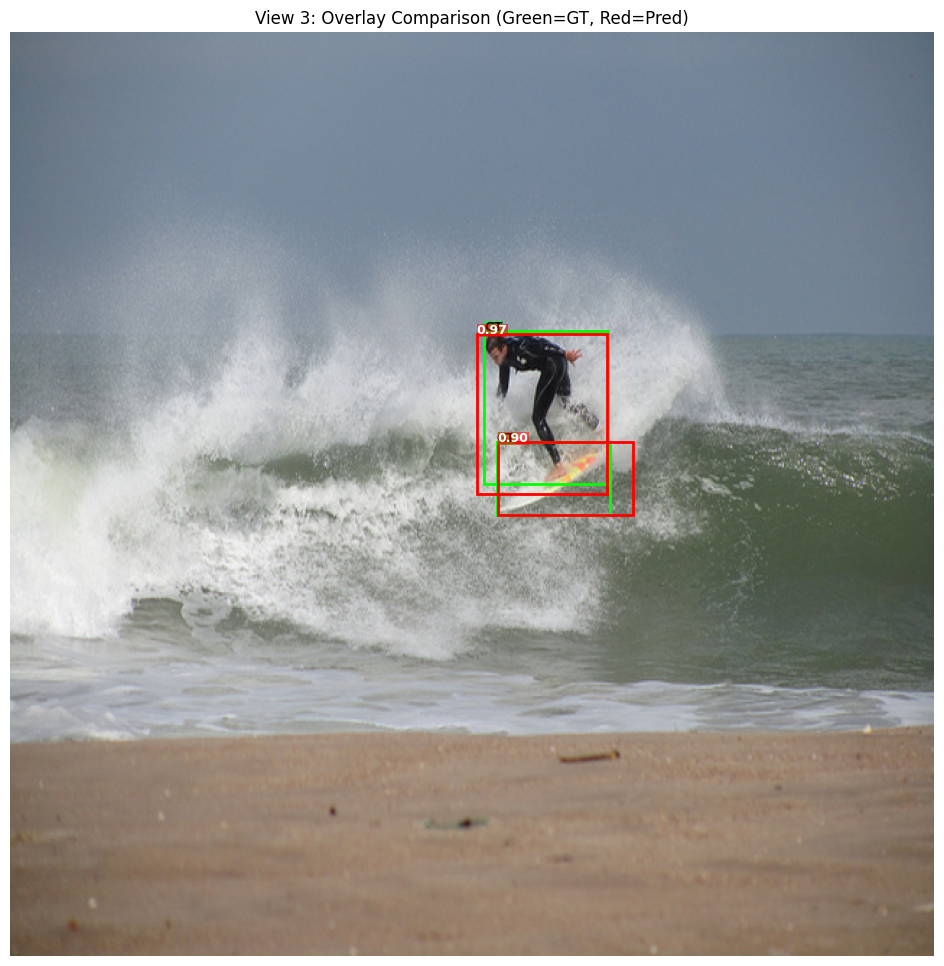
Optimized dataset management and the training pipeline. Trained on 5,000 images and evaluated on 500 test images from a COCO subset, achieving 0.6128 mAP@50, compared with 0.5453 for the YOLOv8s baseline.
Image and text branches merge into vision-language fusion, followed by detection and confidence filtering
Output: surfer and surfboard detections, with ground truth in green and predictions in red

Output — Ground truth (green), predictions (red).


• Pollutant Information Extraction with OCR
Fudan University
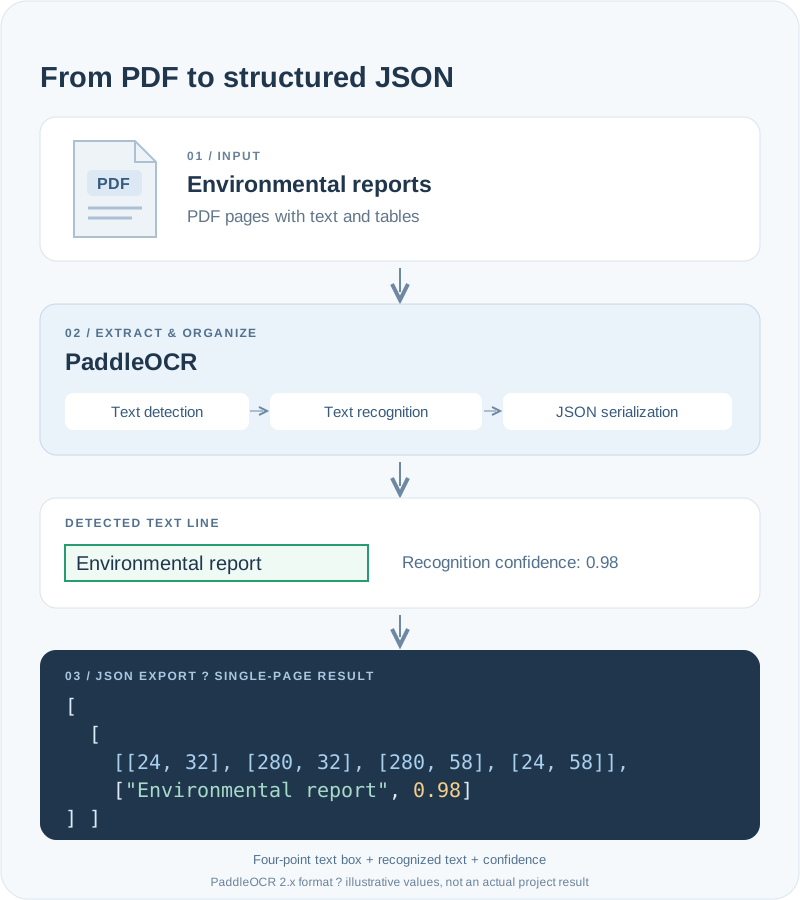
Participation in a text-mining research project on intelligent document processing for environmental regulatory compliance; Design and implementation of an integrated table-parsing solution for information extraction from unstructured enterprise reports; Application of differentiable binarization models for text detection and CRNN-based text recognition for OCR.
Languages & Tools: Python GitHub

• Optimization of Neural Style Transfer
Built a modular Neural Style Transfer system in Python using PyTorch, inspired by Gatys et al. (2016) . Leveraged a pre-trained VGG-19 network to extract content and style features, computed via MSE and Gram matrices. Optimized with L-BFGS over 300–500 iterations, supporting both CPU and GPU. Evaluated VGG19 against ResNet18, and proposed improvements for mobile and web deployment.
Languages & Tools: Python, PyTorch, Torchvision, Pillow (PIL), Matplotlib

• Eye Protection Mode Assistant
Developed a lightweight, browser-wide eye protection mode using Tampermonkey. Implemented a dynamic green light-filter overlay with intensity control via mouse wheel, a floating toggle button, and auto-saved preferences for persistent user experience. Designed to work on nearly all websites while preserving page color hierarchy for better readability. Provided bilingual documentation (EN/CN) and maintained the project through iterative updates.
Languages & Tools: JavaScript, DOM APIs, CSS, Tampermonkey

• Vaccine Reservation System
Designed and implemented a vaccine appointment scheduling system that allows users to create accounts, log in, check caregiver schedules, and reserve appointments through a terminal interface. Developed secure login with password hashing and salting, modeled patients and caregivers, and managed vaccine stock using SQL. Connected the system to a Microsoft Azure SQL database via JDBC.
Languages & Tools: Java, SQL, JDBC, Microsoft Azure GitHub

• Tinyserv: Exploit Analysis & Patch Development
Investigated real-world exploits on a vulnerable HTTP server (tinyserv), performed root-cause analysis, and wrote secure patches to prevent unauthorized access to admin-only pages. Ensured functional correctness and long-term security across both normal and malicious inputs.
Languages & Tools: C, gdb, curl, HTTP GitHub